Designing for Disconnection: How to Build APIs That Survive Australia's Connectivity Gaps
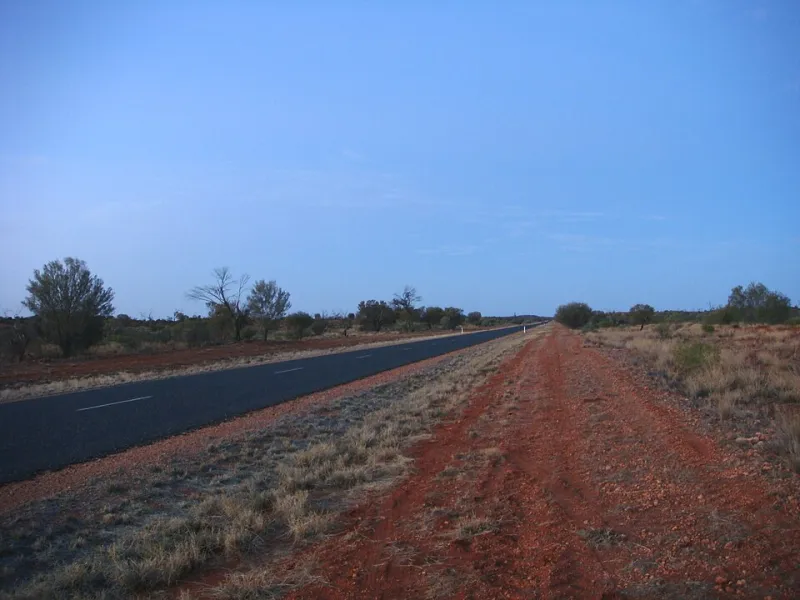
Photo: Jorge Láscar from Australia, CC BY 2.0, via Wikimedia Commons
Drive an hour west of Mackay and the mobile signal becomes intermittent. Drive three hours and it may disappear entirely for stretches. Across vast portions of regional and rural Australia — from the Cape York Peninsula to the Nullarbor, from the Kimberley to outback New South Wales — connectivity is not a given. It is a variable, and sometimes it is zero.
For software developers working primarily in capital cities, this is an abstract concern. For the teams building systems that must function reliably in these environments, it is the central design constraint around which everything else is organised.
This guide is written for developers who need their APIs and client applications to behave sensibly when the internet is unavailable, degraded, or unpredictable. It is also an argument that the engineering discipline required to solve these problems is more sophisticated — and more transferable — than it might initially appear.
Understanding the Connectivity Landscape
Before designing a system for poor connectivity, it helps to understand the specific failure modes you are designing against. In regional Australia, these tend to fall into three categories.
The first is intermittent connectivity — signals that drop and return unpredictably. This is common in areas served by single-tower mobile coverage, where a moving vehicle or a change in weather can interrupt a connection mid-request. The second is degraded connectivity — technically connected, but with latency measured in seconds rather than milliseconds, or with bandwidth so constrained that any non-trivial payload becomes a liability. The third is extended outages — periods of complete disconnection that may last hours or days, caused by infrastructure failures, planned maintenance in remote areas, or natural disasters.
Each failure mode demands a slightly different response from your system architecture. An application that handles intermittent drops gracefully may still behave poorly under sustained low-bandwidth conditions. A system designed for extended outages requires more sophisticated local state management than one built merely to tolerate brief interruptions.
The Offline-First Principle
The conceptual shift at the heart of good connectivity-resilient design is moving from an online-first to an offline-first mental model.
In an online-first architecture, connectivity is assumed. The application attempts to reach a remote API, and failure is treated as an exception — something to handle with an error message and a retry prompt. The local device is essentially stateless; it is a thin client that depends on the server for everything meaningful.
In an offline-first architecture, the local device is treated as the primary source of truth for the current session. It holds a working copy of the data it needs, performs operations against that local copy, and synchronises with the remote API when connectivity is available. Connectivity becomes an enhancement rather than a prerequisite.
This inversion has significant implications for how you design both your client application and your API.
Structuring Your API for Synchronisation
An offline-first client needs an API that supports efficient, incremental synchronisation rather than full data fetches. Several design patterns are particularly useful here.
Delta synchronisation involves designing your API endpoints to return only records that have changed since a given timestamp or cursor. Instead of fetching an entire dataset on every sync, the client sends its last-known sync point and receives only the changes since then. This dramatically reduces the data transferred over constrained connections and makes sync operations fast enough to complete during brief connectivity windows.
A simple implementation might look like a query parameter on your collection endpoints — /api/v1/records?updated_since=2024-11-01T00:00:00Z — returning a paginated list of changed records along with a next_cursor value for subsequent requests. Deleted records should be represented as soft deletes with a deleted_at timestamp rather than removed from the response entirely, so clients can remove them from local storage during sync.
Idempotent writes are essential when clients may submit the same operation multiple times due to failed or uncertain requests. Every mutation endpoint should accept a client-generated idempotency key — typically a UUID generated at the time the operation is created locally. If the same key is submitted twice, the server returns the result of the first successful operation rather than executing the action again. This allows clients to safely retry writes after a dropped connection without risking duplicate records.
Conflict resolution strategies become necessary when multiple clients may modify the same records while offline. The appropriate strategy depends on your domain. Last-write-wins, based on timestamps, is simple to implement but can silently discard legitimate changes. Operational transformation and conflict-free replicated data types (CRDTs) are more sophisticated but may be overkill for many regional business applications. For many use cases, a pragmatic middle ground — flagging conflicts for manual review and notifying the relevant user — is both simpler and more trustworthy than automated resolution.
Graceful Degradation in Practice
Not every application needs full offline capability. For many systems, the appropriate goal is graceful degradation — ensuring that the application remains usable in a reduced capacity when connectivity is lost, rather than failing completely.
This means identifying which operations are genuinely critical and ensuring they can proceed offline, while accepting that less critical functions may be unavailable. A field service application, for instance, might allow technicians to record job completions and capture signatures offline while disabling the ability to create new work orders until connectivity is restored. The critical workflow continues; the non-critical one waits.
Client-side queuing is a practical mechanism for this. Operations performed while offline are stored in a local queue — a persistent data structure in browser storage, SQLite on a mobile device, or a similar mechanism — and submitted to the API when connectivity returns. The queue should be durable across application restarts and should handle partial submission failures gracefully.
Observability Under Constrained Conditions
Monitoring systems that operate in low-connectivity environments presents its own challenges. Traditional real-time observability pipelines assume that log and metric data can be streamed continuously to a central collector. In regional deployments, this assumption fails.
A more resilient approach involves local buffering of telemetry data, with periodic batch uploads when connectivity is available. Error logs and critical events should be prioritised for early transmission; verbose debug logs can be held longer or discarded if storage becomes constrained. Your API should expose a lightweight health endpoint that clients can use to confirm connectivity before attempting larger sync operations.
Turning Constraint into Capability
There is a broader point worth making here. The engineering required to build systems that work reliably in regional Australia — systems that handle disconnection gracefully, synchronise efficiently, and degrade without failing — is not niche or parochial. These are problems that matter anywhere connectivity is uncertain: in aircraft, on vessels, in underground facilities, in disaster response scenarios, and in the rapidly growing number of edge computing deployments where processing happens far from a reliable network.
Development teams based in regional Australia, who have been solving these problems out of necessity for years, possess expertise that is genuinely scarce in the broader industry. The infrastructure gaps that once seemed like a disadvantage are, viewed through the right lens, a forcing function for a category of engineering excellence that is increasingly in demand.
Building for the bush is not a constraint on ambition. It is a foundation for it.